
“Roosevelt was my closest friend,” Taft said brokenly, then wept. On April 25, 1912, a reporter found the president slumped in his train car in Boston. He had spent the day giving speeches against Roosevelt, who had backed Taft for president four years earlier (Figure 1). Everyone knew how a fight like that ends: a vote and a loser. Two statisticians who split in 1935 never got that ending.
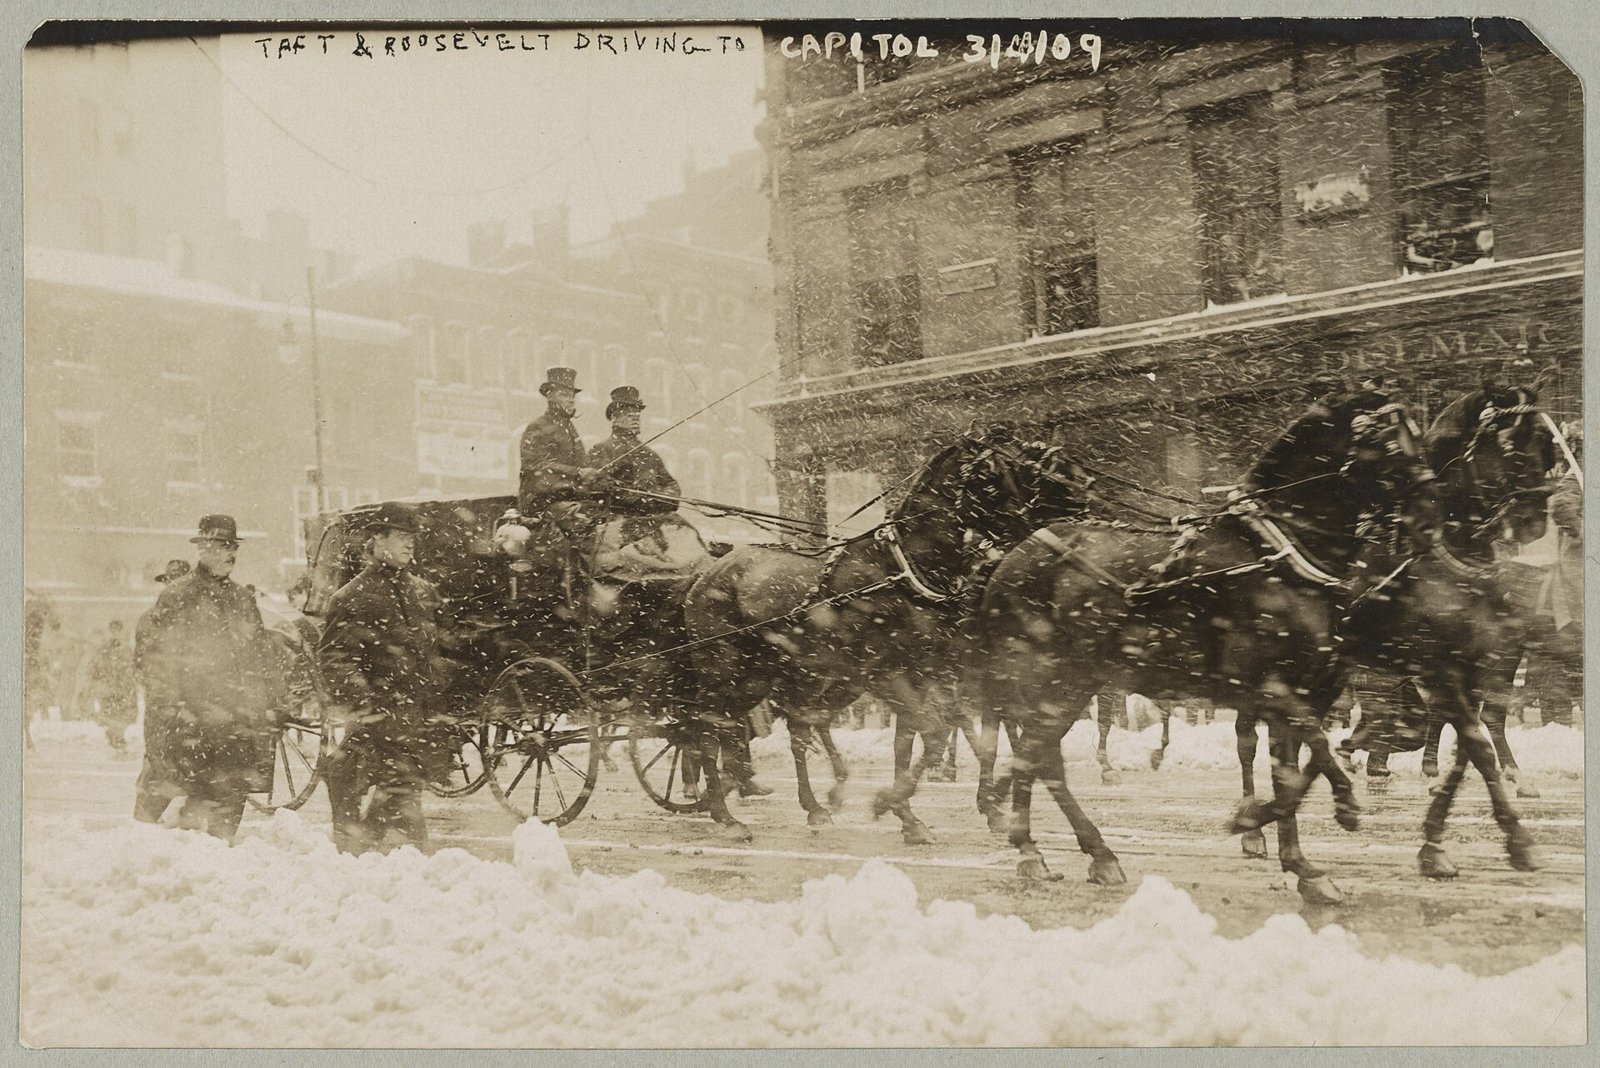
Figure 1. Before the split: Roosevelt rides with Taft to the Capitol through a snowstorm on March 4, 1909, the day he handed Taft the presidency. Bain News Service, Library of Congress. Public domain.
Textbook writers later sewed the two camps’ methods into one, like two pieces of cloth (Figure 2). The seam, where one camp’s question ends and the other’s begins, runs through nearly every introductory statistics class. Anyone who sat through one met Fisher on one side and Neyman and Pearson on the other, without being told which part came from whom.
Figure 2. Two cloths before the seam: a printed square and a plain strip, pinned along the line where they will be sewn. Photo: jeansophie, via Flickr. CC BY 2.0.
Jerzy Neyman stood up to read a paper, and by the time he sat back down, his relation with Fisher had broken. It was March 28, 1935, at the Royal Statistical Society. The paper was on the design of farm experiments and written with two colleagues. Ronald Fisher, who had spent fourteen years at Rothamsted, rose in the discussion and said Dr. Neyman had been “somewhat unwise in his choice of topics.” He added that “before criticizing previous work it is always wise to give enough study to the subject to understand its purpose.” Egon Pearson, Neyman’s collaborator, spoke as well. He would “beg leave to question the wisdom of accusing a fellow worker of incompetence without… showing that he had succeeded in mastering the argument.”
Fisher was once photographed beside the statistician William Sealy Gosset (Figure 3). Gosset called Neyman “the only person except yourself I have heard talk about maximum likelihood as if he enjoyed it.” Maximum likelihood, Fisher’s own method, picks the explanation that makes the data most likely, the way a detective picks the suspect who fits every clue.
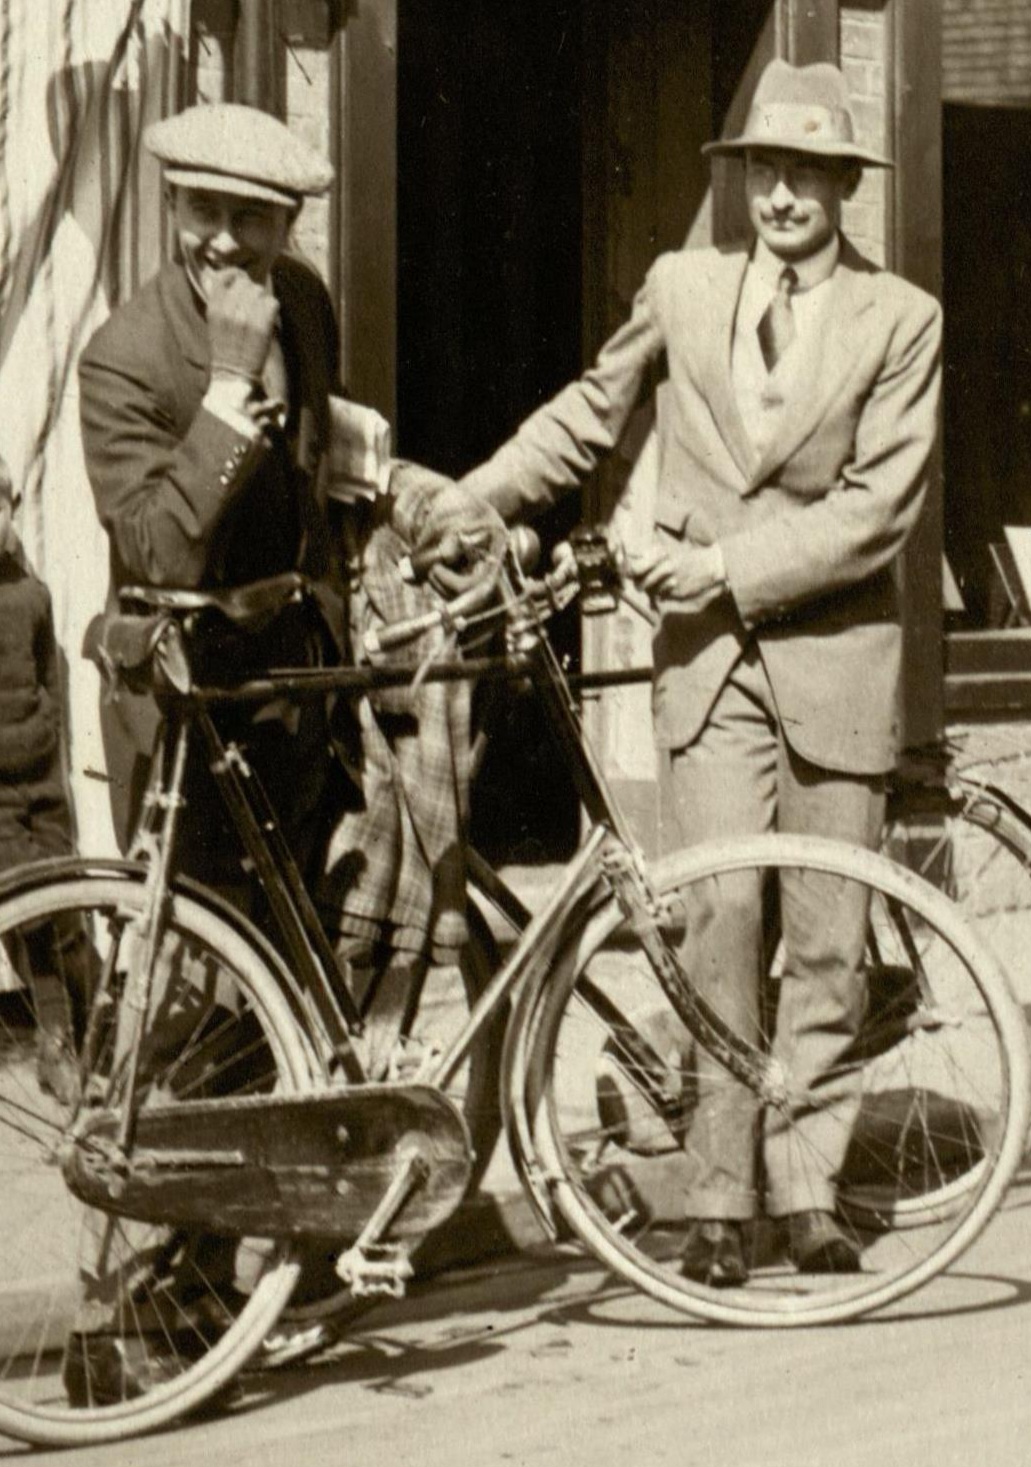
Figure 3. Fisher and Gosset, who published as “Student,” with a bicycle, before 1937. Photographer unknown. Public domain, via Wikimedia Commons.
If I were Fisher, I would feel ambushed, mostly. Someone I had once been warm with had challenged work I had built. Pearson spoke too, skipped the argument, and turned to how I had spoken to Neyman. Losing on the mathematics would have been easier. I left having been told, before I could compose myself, that I had behaved badly while defending my own work.
Most people have seen some version of that meeting. Someone you trained, or trusted, stands up in public against the thing you built. The friendship changed long before, and you find out only as it breaks in front of witnesses.
However, if I were Neyman, I would feel exposed first. I was the one putting a claim in front of the room, and Fisher was not just another audience member. He led the field. First I am told I was unwise to have chosen this topic at all, before I have defended a word of it. Then I am told I misunderstood the very tests I was correcting. Neither line touches my math. And the man saying both is the one whose opinion of my work mattered most.
Both lines are about who outranks whom. If Fisher had said, “here is where your math breaks,” I could answer it. “You misunderstood” leaves me no answer that does not sound defensive. Pearson speaks up for me. Relief, probably, but a complicated kind, because now the room has also watched me need rescuing.
Taft’s fight did get its ending. Woodrow Wilson won the election, and Taft came third, behind even Roosevelt. Fisher and Neyman never got theirs. Neither man conceded, and neither method lost. Gerd Gigerenzer and his coauthors later traced the textbooks’ seam back to its two sources.
You have probably used this stitched method without either name attached. Say a headline on your phone this week reads that a cold remedy “significantly” shortened colds. At the counter you pay twelve dollars for a box that rattles in your coat pocket, then a second box for your partner. “Significantly” there means that a number crossed a fixed line. Fisher would ask how unusual that one result would be if the remedy did nothing. Neyman and Pearson would ask for a rule that, used again and again, misleads you only so often. Before you spent twenty-four dollars, which of the two was the headline answering? The method behind the headline no longer says.
The method reads as one settled thing: state a hypothesis, run the numbers, compare the result to a threshold, decide. It is a truce between two camps who never agreed, stitched together so completely that the seam does not show anymore.
How Far Over, or Over the Line
An officer stands by a sixty-five mile an hour road, holding a beeping radar gun (Figure 4). The first driver passes at eighty, the second at eighty-four, the third at one hundred. Fisher and Neyman–Pearson would agree on how to read the gun. They would disagree on what to write down.
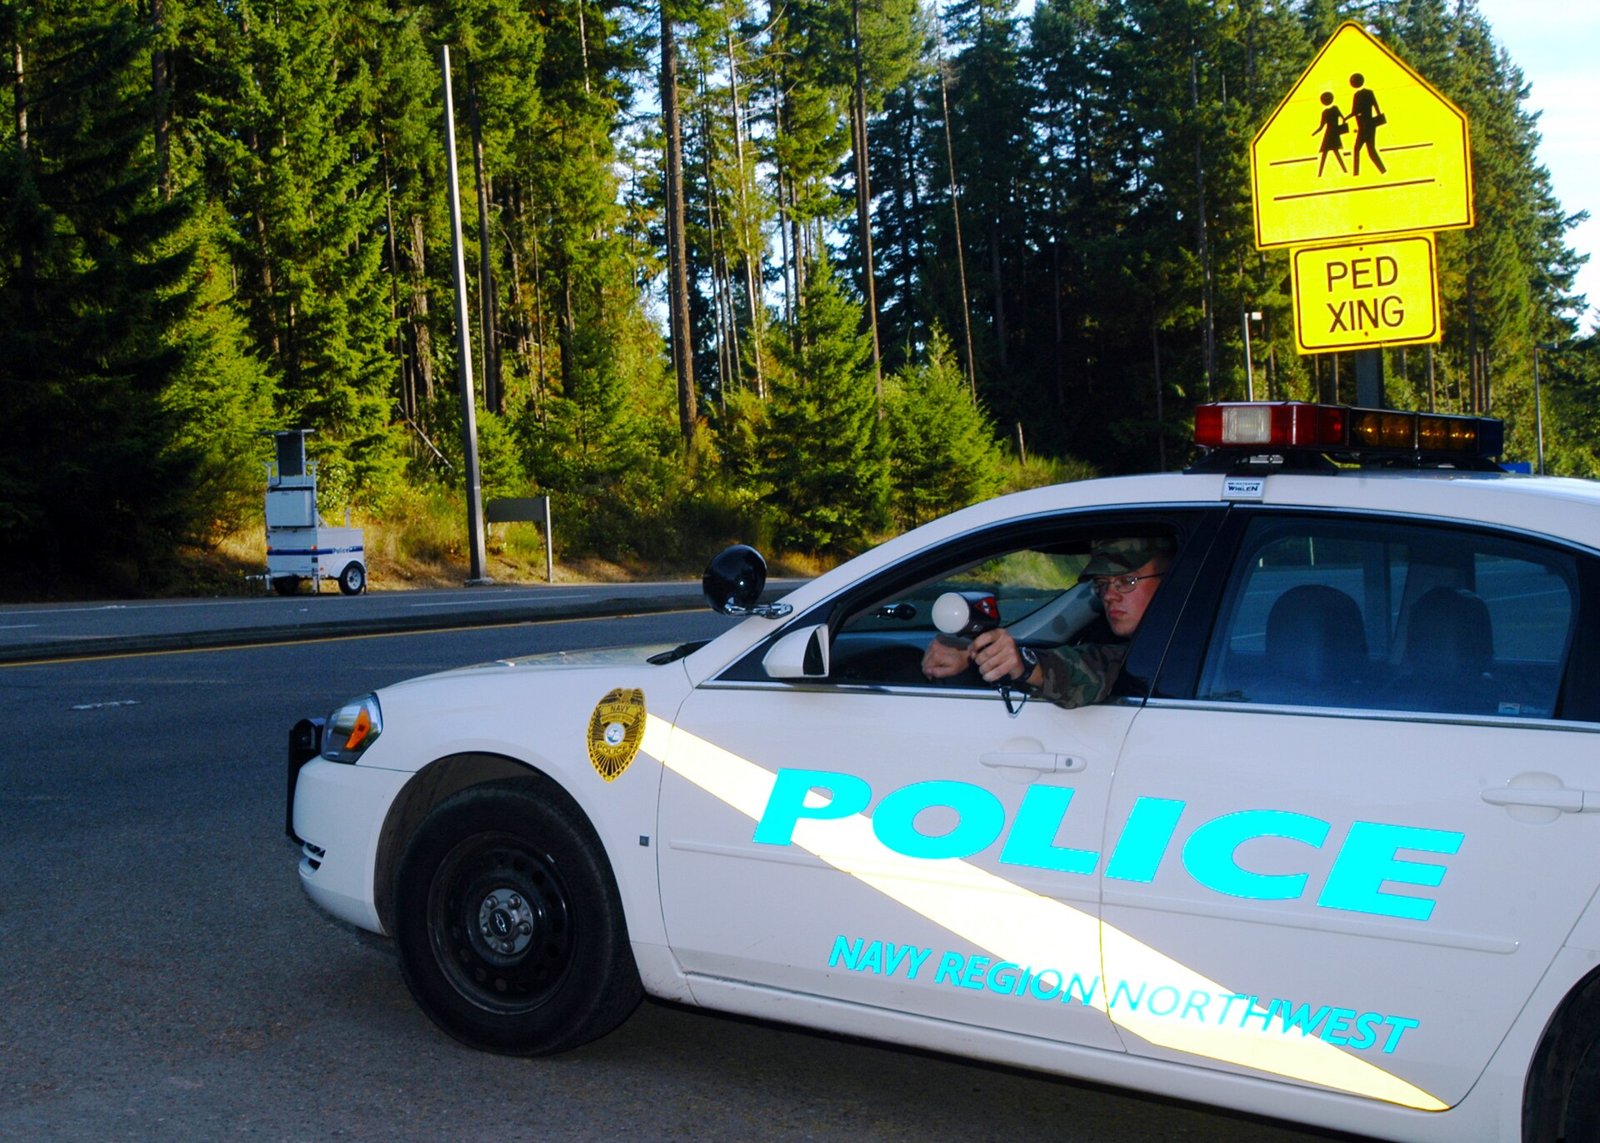
Figure 4. A base security officer tracks speeders at Naval Base Kitsap, Washington, 2006. U.S. Navy photo by Hodges Pone III. Public domain.
Both camps start from the same guess, the null hypothesis: here, that a driver is just keeping pace with traffic. Before any car arrives, both pick one number to compute from each reading, the test statistic. For the radar gun, that number is how far a reading lands above the average speed. Agreement ends there.
Fisher called his significance testing. His vocabulary, null hypothesis and p-value, is worked out cup by cup in a separate piece on the lady tasting tea. A p-value is the chance that a driver keeping pace with traffic would read as fast as the clocked car, or faster. In Fisher’s own words, “every experiment may be said to exist only in order to give the facts a chance of disproving the null hypothesis.” On the road, the gun can show a driver was not keeping pace, and it can never prove one was.
Fisher’s method writes a report that gets worse the faster the driver was going. Eighty in a sixty-five zone reads as mildly over. Eighty-four reads as a firmer flag. One hundred reads as reckless. What Fisher refused to do was name a single speed, fixed for every road, where “a little fast” turns into “reckless.” His test also names no second hypothesis to weigh against the null. Those two refusals were what he would defend for decades.
Neyman–Pearson called theirs hypothesis testing. They asked a question Fisher left open: once a test is built, how often will it be wrong, and in which direction? Their answer names a second hypothesis, the alternative: here, that the driver is speeding. It also names two kinds of error, flagging a driver who was keeping pace and missing one who was speeding. The share of drivers keeping pace that a test is allowed to flag is fixed in advance and written alpha.
Neyman and Pearson also called alpha the significance level of the test, the name Fisher used for his 5 per cent convention. The likeness is only on the surface, Jose Perezgonzalez writes in a 2015 tutorial on teaching the two camps, for three reasons. Neyman and Pearson’s alpha must be set before the data, and Fisher’s level need not be. A Neyman–Pearson test decides between two hypotheses with alpha, where Fisher’s level weighs the evidence against one. And alpha has no shades: a test runs at 0.05 or at 0.01, never both. The errors and alpha are unpacked in the courtroom case built on Glass Onion. On the road, alpha sets a citation line, the rejection region. Every driver over it gets the same ticket, from the slowest speeder to the fastest.
On this road, traffic averages the limit, sixty-five, and speeds spread around it by roughly six and a half. The test statistic, written z, counts how many spreads a reading sits above sixty-five. The driver at eighty lands at z = 2.3. The driver at eighty-four lands at z = 2.9. Fisher separates even those two. A driver keeping pace with traffic reads eighty or faster about 1 time in 93. Eighty-four or faster comes up about 1 in 540. The driver at one hundred would turn up about 1 time in 25 million. Neyman–Pearson fix their cutoff beforehand, with the significance level of the test at 0.05, which puts the rejection region at z > 1.645 (Figure 5). On this road that is near seventy-six, eleven over the limit.
One Test, Two Frameworks
Fisher and Neyman–Pearson run the same test on the same reading, but answer two different questions with it. The grey spine down the middle is the skeleton both camps agree on. The colored cells are where they part.
Fisher
Significance testing
the statistic is a propertyof the sample
Neyman–Pearson
Hypothesis testing
size and power are propertiesof the test
Set the null, H₀.
Set the null H₀, and name the alternative Hₐ.
Fix the test statistic T and its distribution under H₀. Its form is set before any data.
Nothing is fixed in advance.
No line drawn. No alternative to weigh.
Fix the level α and the rejection region R, before a single measurement.
Draw a real sample. Compute T.
Report the p-value: how rare is this reading under H₀? The report sharpens as the reading climbs.
Is T inside R? A yes or no, settled before the data arrived.
Reject H₀ if p is small. Judged fresh each time. The null is left standing, never proved.
If T is in R, reject H₀ and accept Hₐ. The verdict was set before the data.
Inductive inference: a probability statement about this one sample.
Inductive behavior: a guarantee about how often the method misleads, over the long run.
Fisher wanted a probability statement about this one sample, the one reading taken. Neyman–Pearson gave that up, in exchange for a guarantee about how often the method as a whole would mislead, in the long run. That trade is what makes theirs a framework in the strict sense, a decision structure run the same way on every new case. Fisher opposed that kind of decision rule.
Fisher’s objection to the trade had two parts. First, power, the chance a test catches a real effect when there is one, needs an alternative named in advance. For the radar gun, power is the chance it flags a driver who really is speeding, and that depends on how fast the speeder is assumed to go. Naming that speed in advance asks a scientist to know the answer the experiment exists to find. Second, the framework asks a scientist puzzling over one dataset to act like a factory inspector clearing a batch. The inspector’s guarantee covers the batch, never this one sample.
A lab report puts the same split in front of anyone with a patient portal. The cholesterol result opens, and one number has a small red H beside it. That flag works like the citation line: a cutoff drawn before the blood was taken, and a result just over it gets the same H as one far past it. The flag is the verdict half. The other half is missing: how unusual is this one number? Read as a verdict alone, a result just over the line can mean a second blood draw two weeks later, and two weeks of worry. At the next checkup, one question asks for both halves: how far past the line is it?
Where the Ticket Meets the Speed
The officer writes a ticket with both halves: a box checked for over the line, and the speed beside it (Figure 6). A student’s homework mixes them, circling p = 0.03 in pencil and writing “significant” beside it, because it fell under the 0.05 line. That mark belongs to neither camp.
The mark reports a p-value, Fisher’s measure of how unusual the result is, next to a line fixed in advance, Neyman–Pearson’s verdict. That mix is the seam Gigerenzer and his coauthors traced, and they named it hybridization.
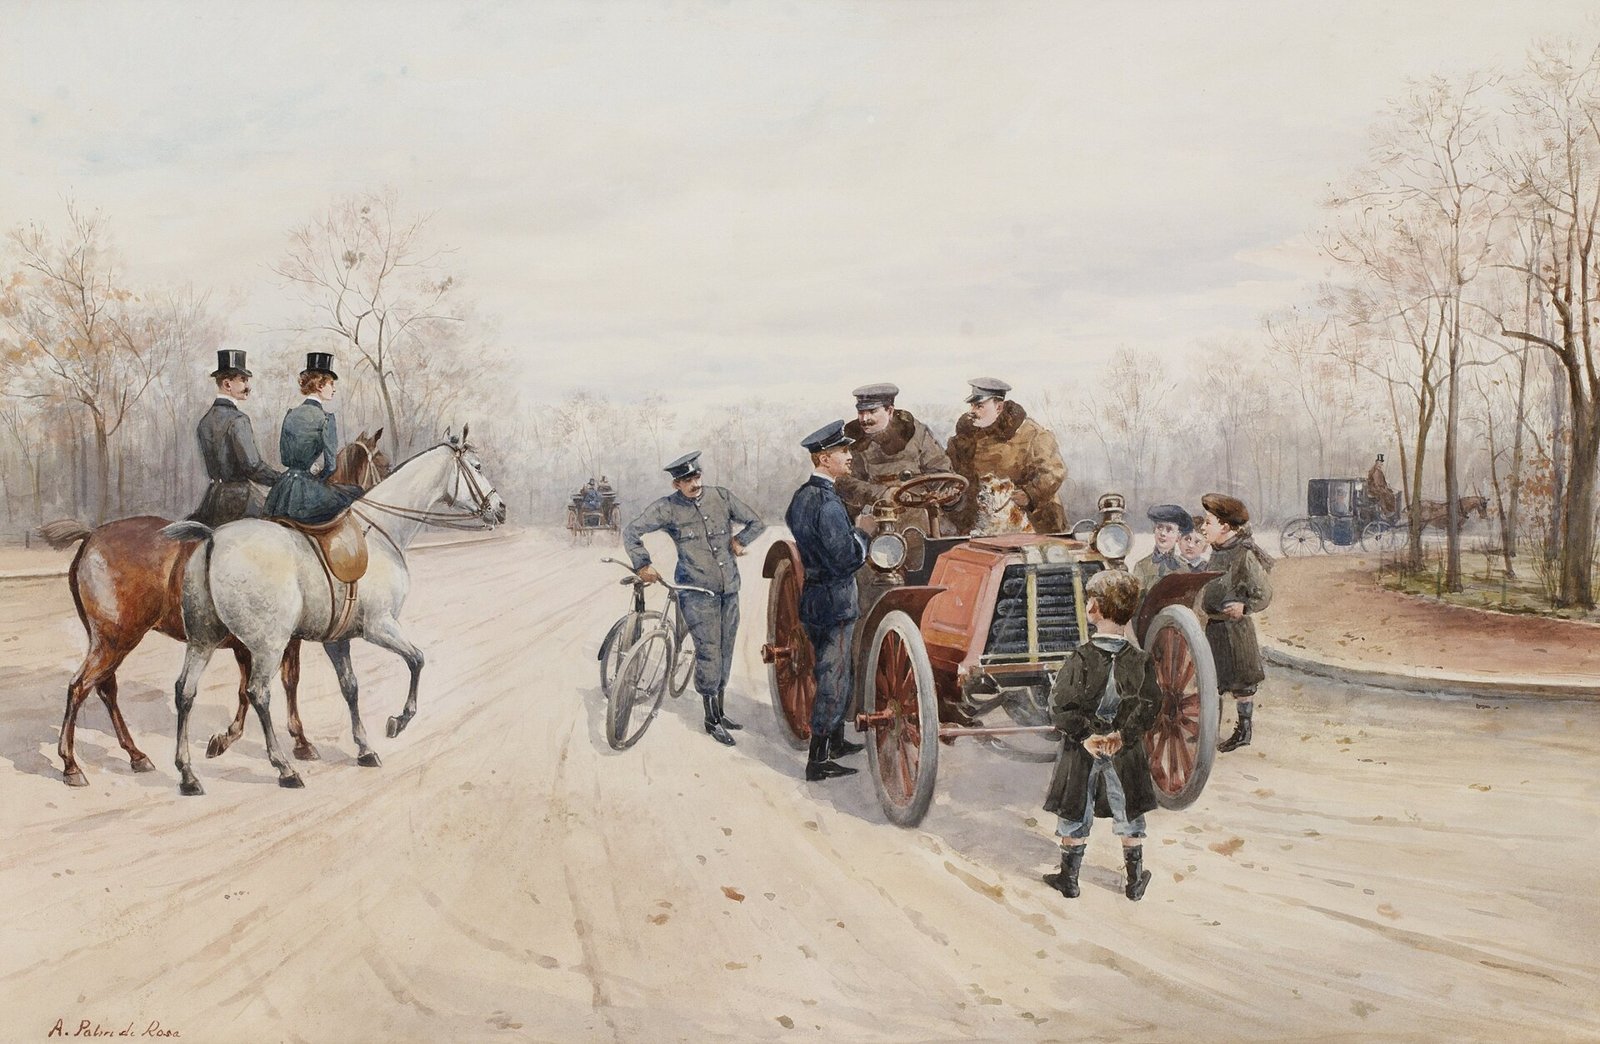
Figure 6. A speeding ticket before radar: police stop an early motorcar in the Bois de Boulogne, Paris, while riders on horseback look on. Anna Palm de Rosa (1859–1924). Public domain, via Wikimedia Commons.
What Neyman took standing up in 1935 grew on both sides. Neyman answered in print in 1941, in the same measure: one of Fisher’s theories, he wrote, was “simply non-existent.” In a 1962 letter, Fisher wrote of “mad Neymanians in California.” Neither side spared the other, and the textbooks taught both halves anyway.
A study reports p = 0.03 beside the 0.05 line, and two readers take away different things. One hears a verdict: reject, move on. The other hears a strength of evidence, about 1 in 33.
In 2003 the statistician James Berger suggested a fix that follows Fisher rather than Neyman. It was one of several, and none became the agreed synthesis. Hybridization, the economist Francisco Louçã wrote in 2008, “remains an open menu for statisticians.”
The cold remedy that rattles in a coat pocket came with the verdict half alone. Bought on the word “significantly,” the two boxes, one for a partner, cost twenty-four dollars a winter for a line crossed, with no size attached. One look before the next box settles which half a headline hands over: does the article give a number, or just the word? That look decides the partner’s box too. A line such as “colds ended a day sooner, p = 0.03” hands over both halves and a size.
Taft’s loss came like the officer’s ticket, the verdict with its size beside it: he lost, and he placed third. With neither method beaten, introductory textbooks now print both methods side by side, one half each, joined at a seam neither camp signed.
A Closing Reflection. The seam is where a verdict set in advance meets a measure of how unusual one result is. Most numbers you meet hand over one half and stay quiet about the other.
- Spot the seam on a lab report. Now, open the last lab report in your patient portal, or the paper one in a kitchen drawer. Which numbers carry a flag, and which fall just past their line? Which flag, read as a verdict alone, would have sent you back for a second blood draw?
- Unpick the seam in significant. Before this week’s shopping, find the last thing you bought because a study said it worked: a pillow, a language app, a running shoe. Did the claim give you a number, or only the word “significant”? A number would have let you weigh the price against the gain. What has the word cost you since?
- Listen for the seam. This week, when the friend or parent who forwards every study headline sends the next one, read it out loud to them, listening for a line crossed or a measure of how rare, before anyone buys a thing. Which half did your friend or parent hear first?
Taft at least got an ending, something to weep over in a train car. Fisher and Neyman got a truce instead. Like the reporter who went back to Taft’s car, ask for both halves, and the seam shows again.
“Significant” is a big word that never says how big. It means a result crossed a line drawn in advance. Before a headline changes what you decide, ask for the number behind the word.

Where This Practice Came From
Pringle had the train-car scene from the reporter who walked in on it. Louis Seibold of the World had gone back to the president’s car to ask a question. Fisher’s and Pearson’s words come from the minutes of the discussion, printed with Neyman’s 1935 paper. Fisher’s 1955 paper came twenty years after that meeting. Before it, he had criticized his opponents in public only twice, and from then on he did not stop. Gigerenzer and his coauthors gave the mixed method its name, hybridization, in a 1989 history of how probability changed science. This piece closes the run after What It Would Take, In Cups, Fisher’s founding story, and One Napkin, Two Fires, the Neyman–Pearson courtroom.
Intellectual Honesty Note. The two “if I were” passages are dramatized. They imagine each man’s side of the 1935 meeting from the documented exchange, not from either man’s own account. The radar speeds, and the spread of about six and a half miles an hour, are invented to fit the sourced z-values. Its p-values are computed one-sided, because the example counts only a reading over the limit. Given two-sided, as the example usually is, they would read as 1 in 47 and 1 in 270. The cold remedy, the speeding ticket, the student’s pencil mark and the lab report are invented scenes. A lab flag is not a formal hypothesis test; it stands in for any line drawn in advance. Fisher’s objection is condensed to two parts. Calling both approaches frameworks follows Louçã (2008).
References
Bain News Service (1909). Taft & Roosevelt driving to Capitol, Mar. 4, 1909 [Photograph]. George Grantham Bain Collection, Library of Congress, https://lccn.loc.gov/00650956. Public domain.
Berger, J. (2003). “Could Fisher, Jeffreys and Neyman Have Agreed on Testing?” Statistical Science, 18(1), 1-32.
Fisher, R.A. (1935a). Contribution to the discussion of J. Neyman, “Statistical problems in agricultural experimentation.” Journal of the Royal Statistical Society Supplement, 2, 154-157.
Fisher, R.A. (1935b). The Design of Experiments. Oliver and Boyd.
Fisher, R.A. (1955). “Statistical Methods and Scientific Induction.” Journal of the Royal Statistical Society, Series B, 17(1), 69-78.
Fisher, R.A., & Gosset, W.S. [Unknown photographer]. (n.d.). Fisher with ‘Student’ [Photograph]. Public domain, via Wikimedia Commons. https://commons.wikimedia.org/wiki/File:Fisher_with_%27Student%27.jpg

Gigerenzer, G., Swijtink, Z., Porter, T., Daston, L., Beatty, J., & Krüger, L. (1989). The Empire of Chance: How Probability Changed Science and Everyday Life. Cambridge University Press.
Gosset, W.S. (1970). Letters from W.S. Gosset to R.A. Fisher, 1915-1936. Issued for private circulation. Dublin: Arthur Guinness.
jeansophie (n.d.). 4. Mark First Strip and Sew [Photograph]. Flickr, https://www.flickr.com/photos/32731310@N00/876061780. CC BY 2.0.
Louçã, F. (2008). “The Widest Cleft in Statistics: How and Why Fisher Opposed Neyman and Pearson.” ISEG/UTL Working Paper 02/2008/DE/UECE.
Neyman, J., with the cooperation of Iwaszkiewicz, K., & Kołodziejczyk, St. (1935). “Statistical Problems in Agricultural Experimentation.” Journal of the Royal Statistical Society Supplement, 2(2), 107-154 (discussion 154-180).
Palm de Rosa, A. (n.d.). Speeding ticket, Bois de Boulogne [Painting]. Via Bukowskis and Wikimedia Commons. Public domain.
Perezgonzalez, J. D. (2015). Fisher, Neyman-Pearson or NHST? A tutorial for teaching data testing. Frontiers in Psychology, 6, 223. https://doi.org/10.3389/fpsyg.2015.00223
Pone, H., III (2006). Master-at-Arms 3rd Class Brandon Pauley uses a radar gun to track speeders on base [Photograph]. U.S. Navy, via Wikimedia Commons. Public domain.
Pringle, H.F. (1939). The Life and Times of William Howard Taft: A Biography. New York: Farrar & Rinehart.